AI Engineer internship at Geodouro · Feb – Jun 2026
RAG + Text-to-SQL Chatbot — Geodouro
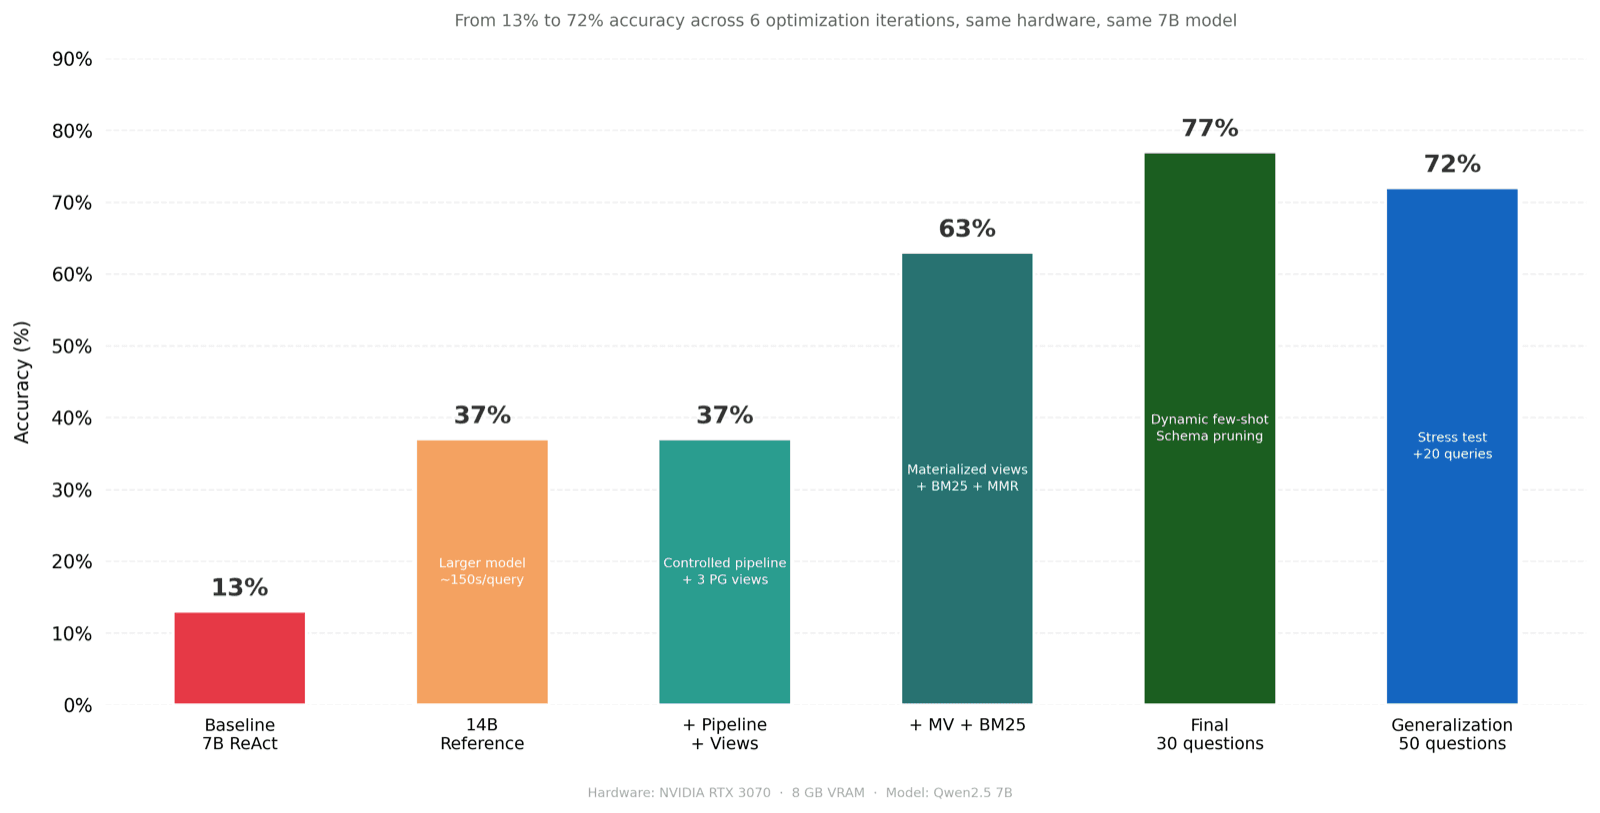
A fully local assistant for Geodouro's agricultural management platform that answers questions from documentation (RAG) and from 3 PostgreSQL databases with 500+ tables (Text-to-SQL). A controlled pipeline with hybrid retrieval and schema pruning took accuracy from 13% to 77%.
Problem
Geodouro builds SIGP, a modular platform for running farms: a field logbook for EU Common Agricultural Policy compliance, vegetation indices (NDVI, NDRE) from drone flights, IoT sensors and a winery module. Farmers and agricultural technicians struggled with the extensive technical documentation, the regulatory terminology and their own data, spread across 3 PostgreSQL databases with more than 500 tables.
The goal was a chatbot that answers both kinds of question, about the platform and about the data, and takes load off the support team. The data is sensitive, so everything had to run locally: no cloud APIs, one consumer GPU (RTX 3070, 8 GB VRAM).
The first approach, a ReAct agent with free access to schema tools, answered only 13% of the company's golden-set questions correctly. It looped until it hit the step limit, picked irrelevant tables and invented column names.
Solution
- A keyword router (100% accurate on 220 test cases, under 1 ms) sends each question to RAG, SQL, both, or a static reply.
- RAG over the platform documentation with hybrid BM25 + MMR retrieval in ChromaDB, plus condensing of follow-up questions using the chat history.
- A controlled five-stage SQL pipeline: domain search, schema pruning to at most four tables, pre-joined (materialized) views, dynamic few-shot examples and SQL generation with Qwen2.5 7B.
- Generated SQL is validated with sqlglot and checked against the real schema; on error the LLM gets one schema-aware retry.
- A LangGraph ReAct agent with five tools (table search, schema lookup, data sampling, SQL execution, join-path discovery over a foreign-key graph) now serves only as a fallback.
- FastAPI backend streaming tokens over Server-Sent Events, with Langfuse tracing and user feedback scoring.
- LLM-as-Judge evaluation (Qwen2.5 14B, binary scoring on four criteria) to measure every optimization against the golden set.
Tech stack
- Python
- LangChain
- LangGraph
- FastAPI
- Qwen2.5 7B
- Ollama
- ChromaDB
- PostgreSQL
- Langfuse
Results
- Accuracy on Geodouro's golden set rose from 13% to 77% on 30 agricultural-practice questions, and reached 72% on all 50, including 20 unseen winery questions.
- The final 7B pipeline beat a 14B reference model by 40 percentage points while answering 10–30× faster (the 14B model took about 150 s per question).
- Median response time of 5.2 s for a single user on one RTX 3070.
- RAG answered all 50 documentation questions in its golden set correctly (3.3 s on average), and the SQL agent produced queries that executed successfully for all 100 test questions across three difficulty levels.
- The internship and project were graded 20/20.